Google's TPU 8tx and 8i Max Split Eighth-Gen Silicon by Workload
Google adds confidential-computing TPU 8tx and dual-chip TPU 8i Max to its eighth-gen lineup, with no cloud availability or pricing yet.
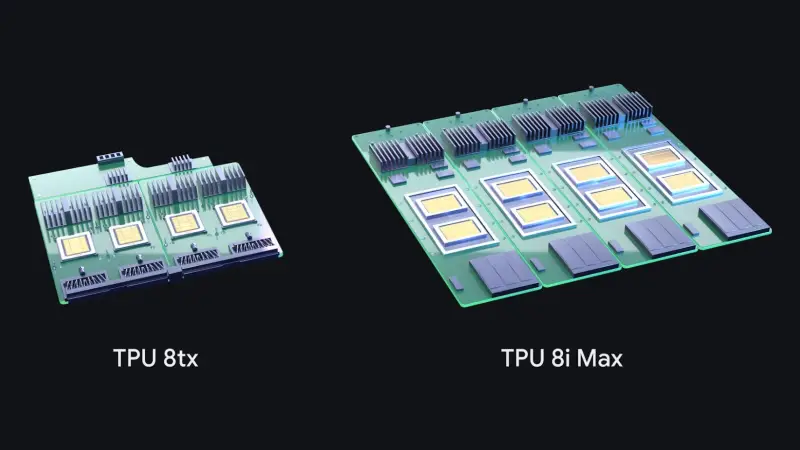
Google has rounded out its eighth-generation TPU range with two new systems, and the more interesting one for most infrastructure teams is probably TPU 8tx. It puts confidential computing into the hardware on the same silicon as the TPU 8t training chip. TPU 8i Max, the other addition, packs two TPU 8i inference chips onto one package. Together they take the lineup from two chips to four systems, and Google says this is the first time it has introduced four TPU systems in a single year.
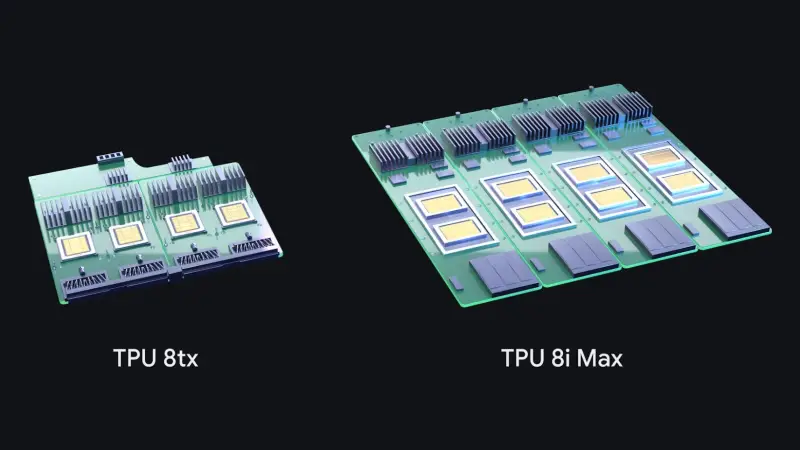
The TPU 8t and TPU 8i were introduced at Cloud Next in April, so these two additions arrive as variations rather than new silicon. Google's argument is that it can change the packaging, high-speed memory, networking and security around an existing chip to suit a particular workload. That approach, the company says, is what lets it stand up specialized configurations in months rather than a full chip cycle. Google also says TPUs now have nearly 100 customers, including frontier labs, trading firms, retailers and universities, and that some of those customers can now deploy TPUs directly in their own data centers.
TPU 8tx: Confidential Computing on TPU 8t Silicon
TPU 8tx reuses the TPU 8t silicon and pairs it with 5th Generation AMD EPYC host CPUs. The distinguishing feature is that confidential computing is built into the hardware, so data and model weights stay protected and isolated while they're being processed, not only at rest or in transit. Google lists PCIe link encryption, cryptographic attestation and secure memory enclaves among the protections. The target audience is regulated enterprises and public-sector bodies that want to run frontier or proprietary models and agents against sensitive data.
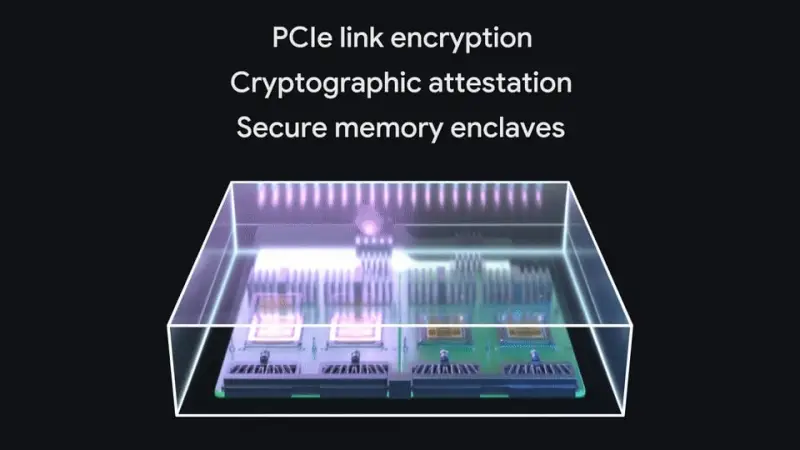
This is where the design gets interesting. TPU 8tx adopts the low-latency Boardfly network Google built for TPU 8i. Google says that delivers up to 2x lower latency than TPU 8t, with what it calls a near-zero performance penalty for the added security. The positioning is secure inference and small-scale training rather than frontier-scale runs. In practice that means a team could fine-tune on private data, distill a large model into a smaller one, or train agents with reinforcement learning without shuttling sensitive data between separate clusters. If you've ever had a compliance review stall a fine-tuning project because the data couldn't leave a trust boundary, you'll see the appeal.
TPU 8i Max: Two Inference Chips per Package
TPU 8i Max is aimed at memory-heavy inference: dozens of agents working across an entire codebase, or hours of video held in context. Google put two TPU 8i chips on one package, doubling compute, on-chip SRAM and HBM bandwidth relative to a single TPU 8i. Google listed 384MB of SRAM for the TPU 8i at launch, which puts the doubled figure at 768MB per 8i Max package by simple arithmetic. Google hasn't stated the package's HBM capacity, so that's the number to ask about before sizing anything.
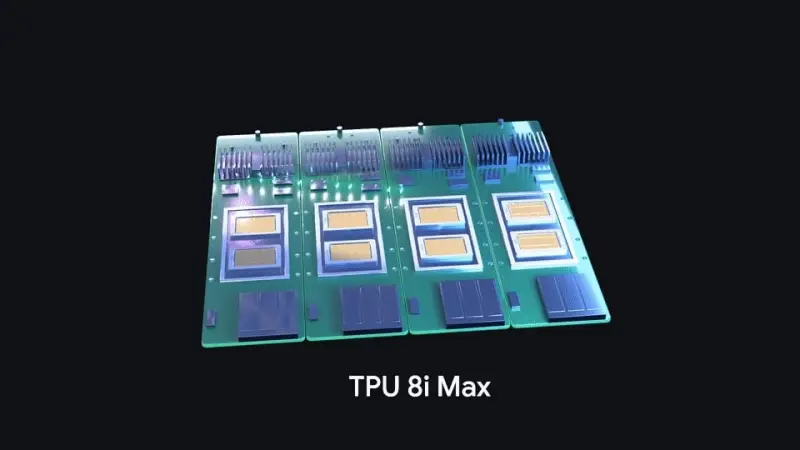
The density claim is the part to test. Because 8i Max fits twice the silicon into the existing rack footprint, Google says it delivers more compute per square foot and per watt. That's a vendor figure, and it will matter most to operators who are power- or floor-space constrained. Here's the thing: density gains only translate into savings if your power and cooling envelope can actually absorb the per-rack load, so the rack-level numbers will matter more than the per-chip ones.
Mapping the Four Systems to Agent Workloads
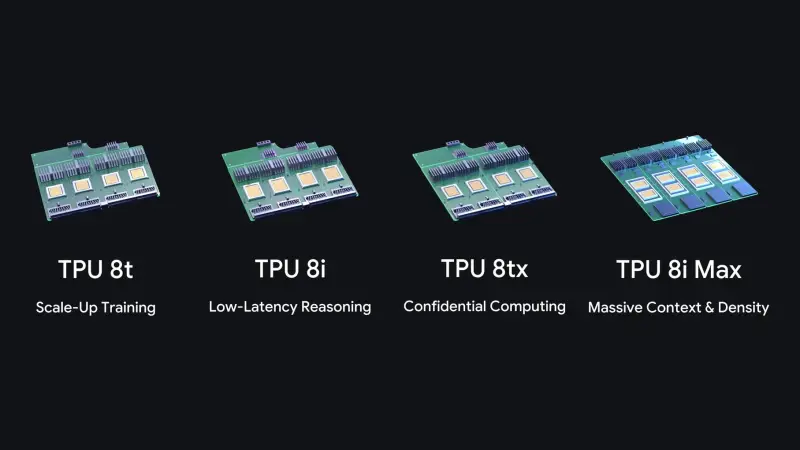
Google now maps the four eighth-generation systems to stages of agent work. TPU 8t handles scale-up training, TPU 8i handles low-latency reasoning, TPU 8tx handles confidential computing, and TPU 8i Max handles massive context windows and the highest compute density per rack. That's a clean story, and it's a useful way to think about procurement, even if the boundaries between categories will blur in real estate planning.
What Google hasn't said is just as important. There's no date yet for when TPU 8tx or TPU 8i Max will reach Google Cloud customers, and no published pricing for either. Until those arrive, both are planning items rather than purchasing decisions.
The Software Stack: TPU Sync, Cloud Pathways and GKE Slicing
Google also open-sourced TPU Sync, a C++ library that treats chip HBM, host DRAM, shared storage and the data center network as a single memory hierarchy. It tiers KV caches off the chip, streams context from prefill nodes to decode nodes, and synchronizes reinforcement learning weights from trainers to samplers. Google says TPU Sync cuts KV transfer latency by more than 90 percent and reduces time to first token by an average of 90 percent on open-weight mixture-of-experts models ranging from 235B to 480B parameters. Those are Google's test results, so treat them as a starting point for your own benchmarking.
Cloud Pathways, the Google DeepMind runtime behind Gemini, is now generally available on Google Kubernetes Engine. It uses a single controller to orchestrate TPU systems across multiple slices for pretraining, reinforcement learning and multihost inference. Long-running jobs stay up through hardware disruptions, with sub-minute slice hot-swapping and elastic resharding.
GKE dynamic slicing is also generally available. It uses optical circuit switching to assemble TPU cubes into larger topologies or split them into smaller isolated workloads without recreating node pools. Google says it cuts job startup times by up to 5x and speeds fault recovery by up to 4.5x. A TPU agent suite in preview plugs into coding tools including Claude Code, Cursor and Google Antigravity to onboard workloads, diagnose bottlenecks and autotune kernels. Separately, the new open-source XLA Serving Engine serves Python-trained models from a C++ runtime across TPUs, GPUs and CPUs.
For most teams, the near-term action is to watch for the 8tx and 8i Max availability announcements and, in the meantime, evaluate whether the GKE and Cloud Pathways features fit your current TPU workloads. The confidential-computing angle on 8tx is the one to flag for security and compliance owners now, since it will shape the architecture review long before a price appears. You can find more on the family at Google Cloud TPU.


